Stop Rebuilding Enterprise Knowledge
for Every AI.

One Enterprise Knowledge & Context Layer for your users, AI assistants, agents and applications.
 

Calculate the Value of Your Enterprise Knowledge

Give AI Knowledge It Can Work With

Finding documents is only the beginning. AI assistants and agents also need to understand which information matters, who can access it, and where it comes from.

Without an enterprise knowledge and context layer, each agent must connect to enterprise systems, search and read content, identify relevant information, check permissions, and find supporting evidence. This repeats work across agents and creates fragmented integrations.
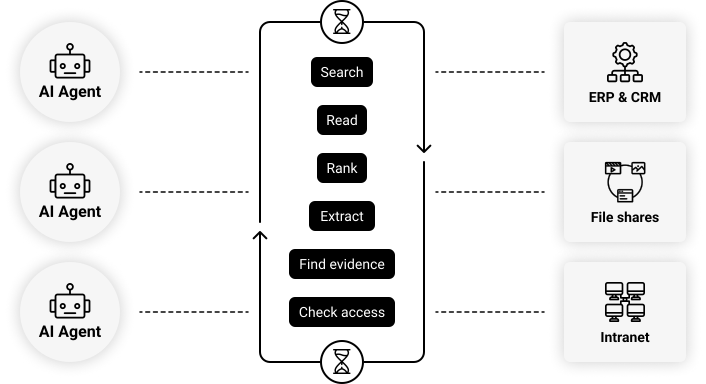
without a shared knowledge layer
Connect Enterprise Knowledge to Any LLM

Connect Enterprise Knowledge to Any LLM

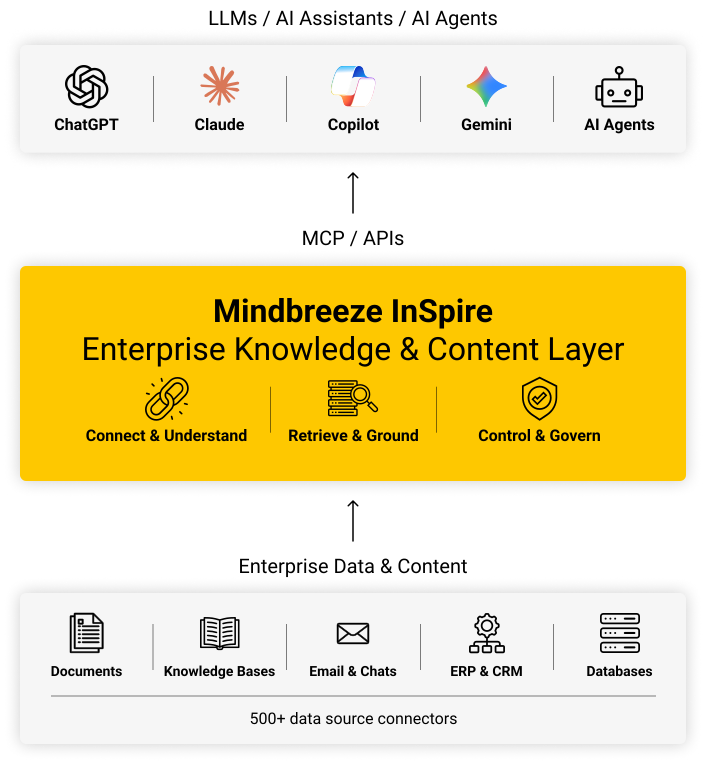
Mindbreeze InSpire provides a reusable enterprise knowledge and context layer, delivering relevant, permission-aware context grounded in your enterprise sources.

This reduce time spent searching for information, reviewing documents, and completing knowledge-intensive tasks.

Reduce unnecessary information processing by providing AI with relevant enterprise context.

AI assistants and agents can draw on a shared knowledge foundation across the AI experiences your organization chooses.

What Could Better Context save you?

Adjust a few parameters to estimate your potential time savings, cost reductions, and return on investment.


Your inputs

Choose an example to start
How much human time does each task take?

Your estimate of active work, including checking and correcting answers.

Example assumptions are included

70% of tasks covered · $60/hour · 40% capacity realized · $3,000/month + $15,000 setup.

Token use and improvement estimates are examples, not measured Mindbreeze results.

Model, tokens & costs

AI model & token use

$2 input · $10 output / 1M tokensStandard global API prices · Verified 2026-11-10 · Dated snapshotView provider pricing ↗

Standard direct API. Choose the billed context tier for each scenario below.

Per completed taskBeforeWith InSpire
Input tokens
Output tokens

Count all model calls and retries per completed task. Compare equivalent answer quality.

Adoption & investment

0%100%
Context tiers, caching & provider fees

Choose the tier for the requests behind your task totals. If a scenario mixes short and long requests, use Custom with weighted effective rates. Task totals are not used to infer a per-request tier.

Covered workloadBeforeWith InSpire
Cache reads (% of input)
Cache writes (% of input)

Reads and writes are disjoint shares of total input, not extra tokens. Each side must total 100% or less. The remaining input uses the uncached rate. Include billable reasoning/thinking in output tokens.

Monthly cached M token-hours
Other API fees ($/month)

Storage and extra API fees are monthly totals for the covered workload, including grounding or tool charges. 1M cached tokens retained for 10 hours = 10 M token-hours. Do not also include these amounts in the recurring platform-cost field.

Include licensing, hosting, ingestion, indexing, embeddings and operations in recurring costs; implementation and training in setup. Avoid double-counting API fees. Positive time savings are valued only at the realization percentage; additional work is charged in full.

Results update automatically. No email required.

Ready to Turn Potential into Results?

Your AI Will Change. Your Enterprise Knowledge Won't.

Build your Enterprise Knowledge & Context Layer once. Make trusted, permission-aware enterprise knowledge available to the AI assistants, agents and applications you choose.

Reduce AI integration complexity. Improve productivity. Scale AI with confidence.

Loading form…